Modelling Loan Default Data of German Customers: Predictive Machine Learning Studies
DOI:
https://doi.org/10.33003/fjs-2026-1023-6193Keywords:
Loan Default, Logistics regression, Random ForestAbstract
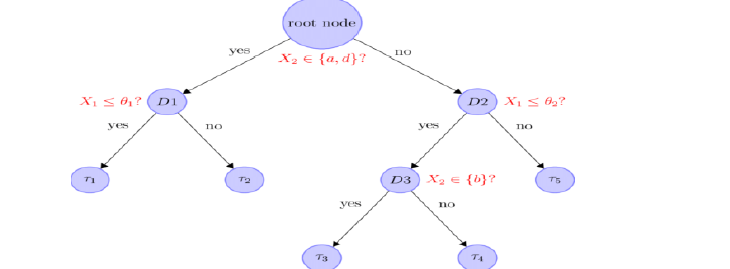
This study considered logistic regression and random forest models in modelling the loan default data of German Customers. The data were randomly partitioned into an 80% training set and a 20% test set. The train set was used to fit the data, while the test set served as the out-of-sample data used to evaluate the performance of the model. On the train set, the random forest performs better than the logistic regression model across all the evaluation metrics. On the test dataset, the random forest has superior specificity, precision, accuracy, and F1-score, but the logistic regression model produced a better sensitivity. This means that the model was better at identifying a bad loan; this is, in fact, the desire and priority of every financial institution – a model that is capable of detecting the risk of loan default. In terms of efficiency, the logistic regression model produced lower variance than the random forest, which had high variance.
References
Aballey, F. (2009). “Bad Loan Portfolio: A Case Study of Agricultural Development Bank”, KNUST.
Anioke, C. N. (2012). Loan Granting And Its Recovery Problems On Commercial Banks (A Case Study Of First Bank Plc, Ojo- Alaba Branch).
Baesens, B., Setiono, R., Mues, C., & Vanthienen, J. (2003). Using neural network rule extraction and decision tables for credit-risk evaluation, Management Science, 49(3), 312-329.
Breiman, L. (2001). Random Forests. Machine Learning volume, 45, 5-32.
Daria, G. and Johan, A. (2013). Interest Rates and Default in Unsecured Loan Markets. Quantitative Finance. (1925-1934), 13(12).
Daria, G. and Johan, A. (2019). Loan Default Prediction using Supervised Machine Learning Algorithms. pp.1.
Evusa, Z., Mudaki, J. S., and Ojala, D. O. (2015). Evaluation of the Factors Leading to Loan Default at Equity Bank, Kenya. Journal of Economics and Sustainability. Vol.6(ISSN 2224-607X), 8.
Hand, D. J., & Henley, W. E. (1997). Statistical classification methods in consumer credit scoring: A review. Journal of the Royal Statistical Society, Series A – Statistics in Society, 160(3), 523-541.
Hastie, T., Tibshirani, R., & Friedman, J. (2009). The elements of statistical learning: data mining, inference and prediction. Springer.
Koh, H. C., & Chan, K. L. (2002). Data mining and customer relationship marketing in the banking industry. Singapore Management Review, 24(2), 1-27.
KPMG. (2002). An analysis of the impact of external debt on banks’ performance. Evidence from Nigeria. British Journal of Arts and Social Sciences., 12(1), 37-51.
Kugiel, L., & Jakobsen, M. (2009). Fund Transfer Pricing in a Commercial Bank. Master's 454 Thesis, MSC in Finance and International Business.
Lee, T. S., Chiu, C. C., Lu, C. J., & Chen, I. F. (2002). Credit scoring using the hybrid neural discriminant technique. Expert Systems with Applications, 23(3), 245-254.
Liang, D., Tsai, C.-F., Dai, A.-J., & Eberle, W. (2018). A novel classifier ensemble approach for financial distress prediction. Knowledge and Information Systems, 54.2, 437-462.
Lu, H., Wang, H., & Yoon, S. W. (2017). Real Time Credit Card Default Classification Using Adaptive Boosting-Based Online Learning Algorithm. IIE Annual Conference. Proceedings. Institute of Industrial and Systems Engineers (IISE).
Murray, J. (2011). Default on a loan. United States Business Law and Taxes Guide.
Paolo, G. (2001). Bayesian data mining, with application to benchmarking and credit scoring. Applied Stochastic Models in Business and Society, 17, 69-81.
Ronaghan, S. (2018). The Mathematics of Decision Trees, Random Forest and Feature Importance in Scikit-learn and Spark.
Sheikh, R. I., William, E., & Sheikh, K. G. (2018). Credit Default Mining Using Combined Machine Learning and Heuristic Approach.
Thomas, L. C. (2000). A survey of credit and behavioral scoring: Forecasting financial risk of lending to consumers. International Journal of Forecasting, 16, 149–172.
Thomas, L. C. Tong E. N., & Mues. C. (2012). “Mixture cure models in credit scoring: If and when borrowers default”. European Journal of Operational Research, 218, 132-139.
White, A. (2020, October 12). What are checking accounts. Retrieved from Select: https://www.cnbc.com/select.
Wikipedia. (n.d.). Decision tree learning. Retrieved July 10, 2021, from Wikipedia: https://en.wikipedia.org/wiki.
Yeh, I.-C., & Lien, C.-h. (2009). The comparisons of data mining techniques for the predictive accuracy of probability of default of credit card clients. Expert Systems with Applications, 36(2), 2473-2480.
Downloads
Published
Issue
Section
Categories
License
Copyright (c) 2026 Emmanuel Idowu Olamide

This work is licensed under a Creative Commons Attribution 4.0 International License.