HausaHateData: A Manually Annotated Multi-Source Dataset for Hausa Hate Speech Detection with Benchmark Evaluation Using XLM-RoBERTa-Large, AfriBERTa and mBERT
DOI:
https://doi.org/10.33003/fjs-2026-1023-6499Keywords:
Hausa, Hate speech detection, Low-resource languages, Dataset construction, African languages, XLM-RoBERTa-Large, AfriBERTa, mBERTAbstract
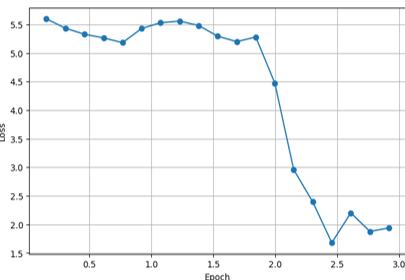
Automated hate speech detection has advanced considerably for high-resource languages, but the availability of manually annotated resources for Hausa remains limited. This study presents HausaHateData, a multi-source corpus of 6,509 unique Hausa-language text instances collected from Twitter, Facebook, the AfriHate corpus, and other publicly available sources. Each instance was assigned a binary label of hate speech or non-hate speech. Trigger-word annotations were added to hate-speech instances where a relevant word or phrase could be identified, and all instances were assigned a positive or negative sentiment label. Two annotators independently labelled the data, producing an observed agreement of 82.99% and a Cohen’s kappa coefficient of approximately 0.65 before disagreements were resolved through discussion. The final corpus contains 2,565 hate-speech instances (39.41%) and 3,944 non-hate-speech instances (60.59%). To establish benchmark results, XLM-RoBERTa-Large, AfriBERTa and multilingual BERT (mBERT) were fine-tuned for binary classification. At the reported final epoch, mBERT achieved the highest accuracy (96.08%) and precision (98.73%), while AfriBERTa achieved the highest recall (94.15%), F1-score (94.89%) and ROC-AUC (0.977). XLM-RoBERTa-Large recorded an accuracy of 94.93% and an F1-score of 93.25%. These results provide initial benchmark evidence for Hausa hate-speech classification and demonstrate the potential value of HausaHateData for further research on low-resource African language processing. The experimental split and confusion-matrix values should be confirmed against the original prediction files before publication.
References
Adam, F. M., Zandam, A. Y., & Inuwa-Dutse, I. (2023). Detection and analysis of offensive online content in Hausa language. arXiv preprint arXiv:2311.10541.
Alabi, J., Adelani, D. I., Mosbach, M., & Klakow, D. (2022). Adapting pre-trained language models to African languages via multilingual adaptive fine-tuning. In Proceedings of the 29th International Conference on Computational Linguistics (pp. 4336–4349).
Arora, A., Nakov, P., Hardalov, M., Sarwar, S. M., Nayak, V., Dinkov, Y., ... & Augenstein, I. (2023). Detecting harmful content on online platforms: What platforms need vs. where research efforts go. ACM Computing Surveys, 56(3), 1–17. https://doi.org/10.1145/360339
Bäumler, J., Blöcher, L., Frey, L. J., Chen, X., Bayer, M., & Reuter, C. (2026). A survey of machine learning models and datasets for the multi-label classification of textual hate speech in English. ACM Transactions on Knowledge Discovery from Data, 20(6), 1–39. https://doi.org/10.1145/382077
Corazza, M., Menini, S., Cabrio, E., Tonelli, S., & Villata, S. (2020). A multilingual evaluation for online hate speech detection. ACM Transactions on Internet Technology, 20(2), 1–22.
Davani, A. M., Díaz, M., & Prabhakaran, V. (2022). Dealing with disagreements: Looking beyond the majority vote in subjective annotations. Transactions of the Association for Computational Linguistics, 10, 92–110. https://doi.org/10.1162/tacl_a_00449
Davani, A. M., Atari, M., Kennedy, B., & Dehghani, M. (2023). Hate speech classifiers learn normative social stereotypes. Transactions of the Association for Computational Linguistics, 11, 300–319. https://doi.org/10.1162/tacl_a_00550
Davidson, T., Warmsley, D., Macy, M., & Weber, I. (2017). Automated hate speech detection and the problem of offensive language. Proceedings of the International AAAI Conference on Web and Social Media, 11(1), 512–515.
Dehghan, S., Umut Sen, M., & Yanikoglu, B. (2025). Dealing with annotator disagreement in hate speech classification. arXiv preprint arXiv:2502.08266. https://doi.org/10.48550/arXiv.2502.08266
Hershcovich, D., Frank, S., Lent, H., De Lhoneux, M., Abdou, M., Brandl, S., ... & Søgaard, A. (2022). Challenges and strategies in cross-cultural NLP. In Proceedings of the 60th Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers) (pp. 6997–7013). https://doi.org/10.18653/v1/2022.acl-long.482
Katyshev, A., Anikin, A., & Zubankov, A. (2023). Bidirectional transformers as a means of efficient building of knowledge bases: A case study with XLM-RoBERTa. In Novel & Intelligent Digital Systems Conferences (pp. 292–297). Springer Nature Switzerland.
Landis, J. R., & Koch, G. G. (1977). The measurement of observer agreement for categorical data. Biometrics, 33(1), 159–174.
Li, Y., Zhang, H., & Chen, X. (2026). Large language models for abusive language detection: Advances and challenges. IEEE Access, 14, 56789–56805.
Maity, K., Ghosh, N., Jain, R., Saha, S., & Bhattacharyya, P. (2025). StereoHate: Toward identifying stereotypical bias and target group in hate speech detection. Natural Language Processing, 31(2), 415–434. https://doi.org/10.1017/nlp.2024.29
Mathew, B., Saha, P., Yimam, S. M., Biemann, C., Goyal, P., & Mukherjee, A. (2021). HateXplain: A benchmark dataset for explainable hate speech detection. In Proceedings of the AAAI Conference on Artificial Intelligence, 35(17), 14867–14875.
Muhammad, S. H., Abdulmumin, I., Ayele, A. A., Adelani, D. I., Ahmad, I. S., Aliyu, S. M., ... & Ousidhoum, N. (2025). AfriHate: A multilingual collection of hate speech and abusive language datasets for African languages. In Proceedings of the 2025 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers) (pp. 1854–1871). https://doi.org/10.48550/arXiv.2501.08284
Muhammad, F. A., Hassan, S. M., & Inuwa-Dutse, I. (2025). Dataset creation and baseline models for sexism detection in Hausa. arXiv preprint arXiv:2510.27038. https://doi.org/10.48550/arXiv.2510.27038
Nekoto, W., Marivate, V., Matsila, T., Fasubaa, T., Fagbohungbe, T., Akinola, S. O., ... & Bashir, A. (2020). Participatory research for low-resourced machine translation: A case study in African languages. In Findings of the Association for Computational Linguistics: EMNLP 2020 (pp. 2144–2160).
Ogueji, K. (2022). AfriBERTa: Towards viable multilingual language models for low-resource languages. http://hdl.handle.net/10012/18662
Saleh, H., Alhothali, A., & Moria, K. (2023). Detection of hate speech using BERT and hate speech word embedding with deep model. Applied Artificial Intelligence, 37(1). https://doi.org/10.1080/08839514.2023.2166719
Sawant, M., Younus, A., Caton, S., & Qureshi, M. A. (2024). Using explainable AI (XAI) for identification of subjectivity in hate speech annotations for low-resource languages. In Proceedings of the 4th International Workshop on Open Challenges in Online Social Networks (pp. 10–17). https://doi.org/10.1145/3677117.3685006
Vargas, F., Guimarães, S., Muhammad, S. H., Alves, D., Ahmad, I. S. I., Abdulmumin, I., ... & Benevenuto, F. (2024). HausaHate: An expert annotated corpus for Hausa hate speech detection. In Proceedings of the 8th Workshop on Online Abuse and Harms (pp. 52–58).
Yu, Z., Sen, I., Assenmacher, D., Samory, M., Fröhling, L., Dahn, C., ... & Wagner, C. (2025). The unseen targets of hate: A systematic review of hateful communication datasets. Social Science Computer Review, 43(5), 1114–1144.
Zampieri, M., Malmasi, S., Nakov, P., Rosenthal, S., Farra, N., & Kumar, R. (2019). SemEval-2019 Task 6: Identifying and categorizing offensive language in social media (OffensEval). In Proceedings of the 13th International Workshop on Semantic Evaluation (pp. 75–86).
Ogueji, K., Zhu, Y., & Lin, J. (2021). Small data? No problem! Exploring the viability of pretrained multilingual language models for low-resourced languages. In Proceedings of the 1st Workshop on Multilingual Representation Learning (pp. 116–126). Association for Computational Linguistics. https://doi.org/10.18653/v1/2021.mrl-1.11
Vargas, F., Guimarães, S., Muhammad, S. H., Alves, D., Ahmad, I. S., Abdulmumin, I., Mohamed, D., Pardo, T., & Benevenuto, F. (2024). HausaHate: An expert annotated corpus for Hausa hate speech detection. In Proceedings of the 8th Workshop on Online Abuse and Harms (pp. 52–58). Association for Computational Linguistics. https://doi.org/10.18653/v1/2024.woah-1.5
Downloads
Published
Issue
Section
Categories
License
Copyright (c) 2026 Bashir Idris Sulaiman, Muhammad Aminu Ahmad

This work is licensed under a Creative Commons Attribution 4.0 International License.